
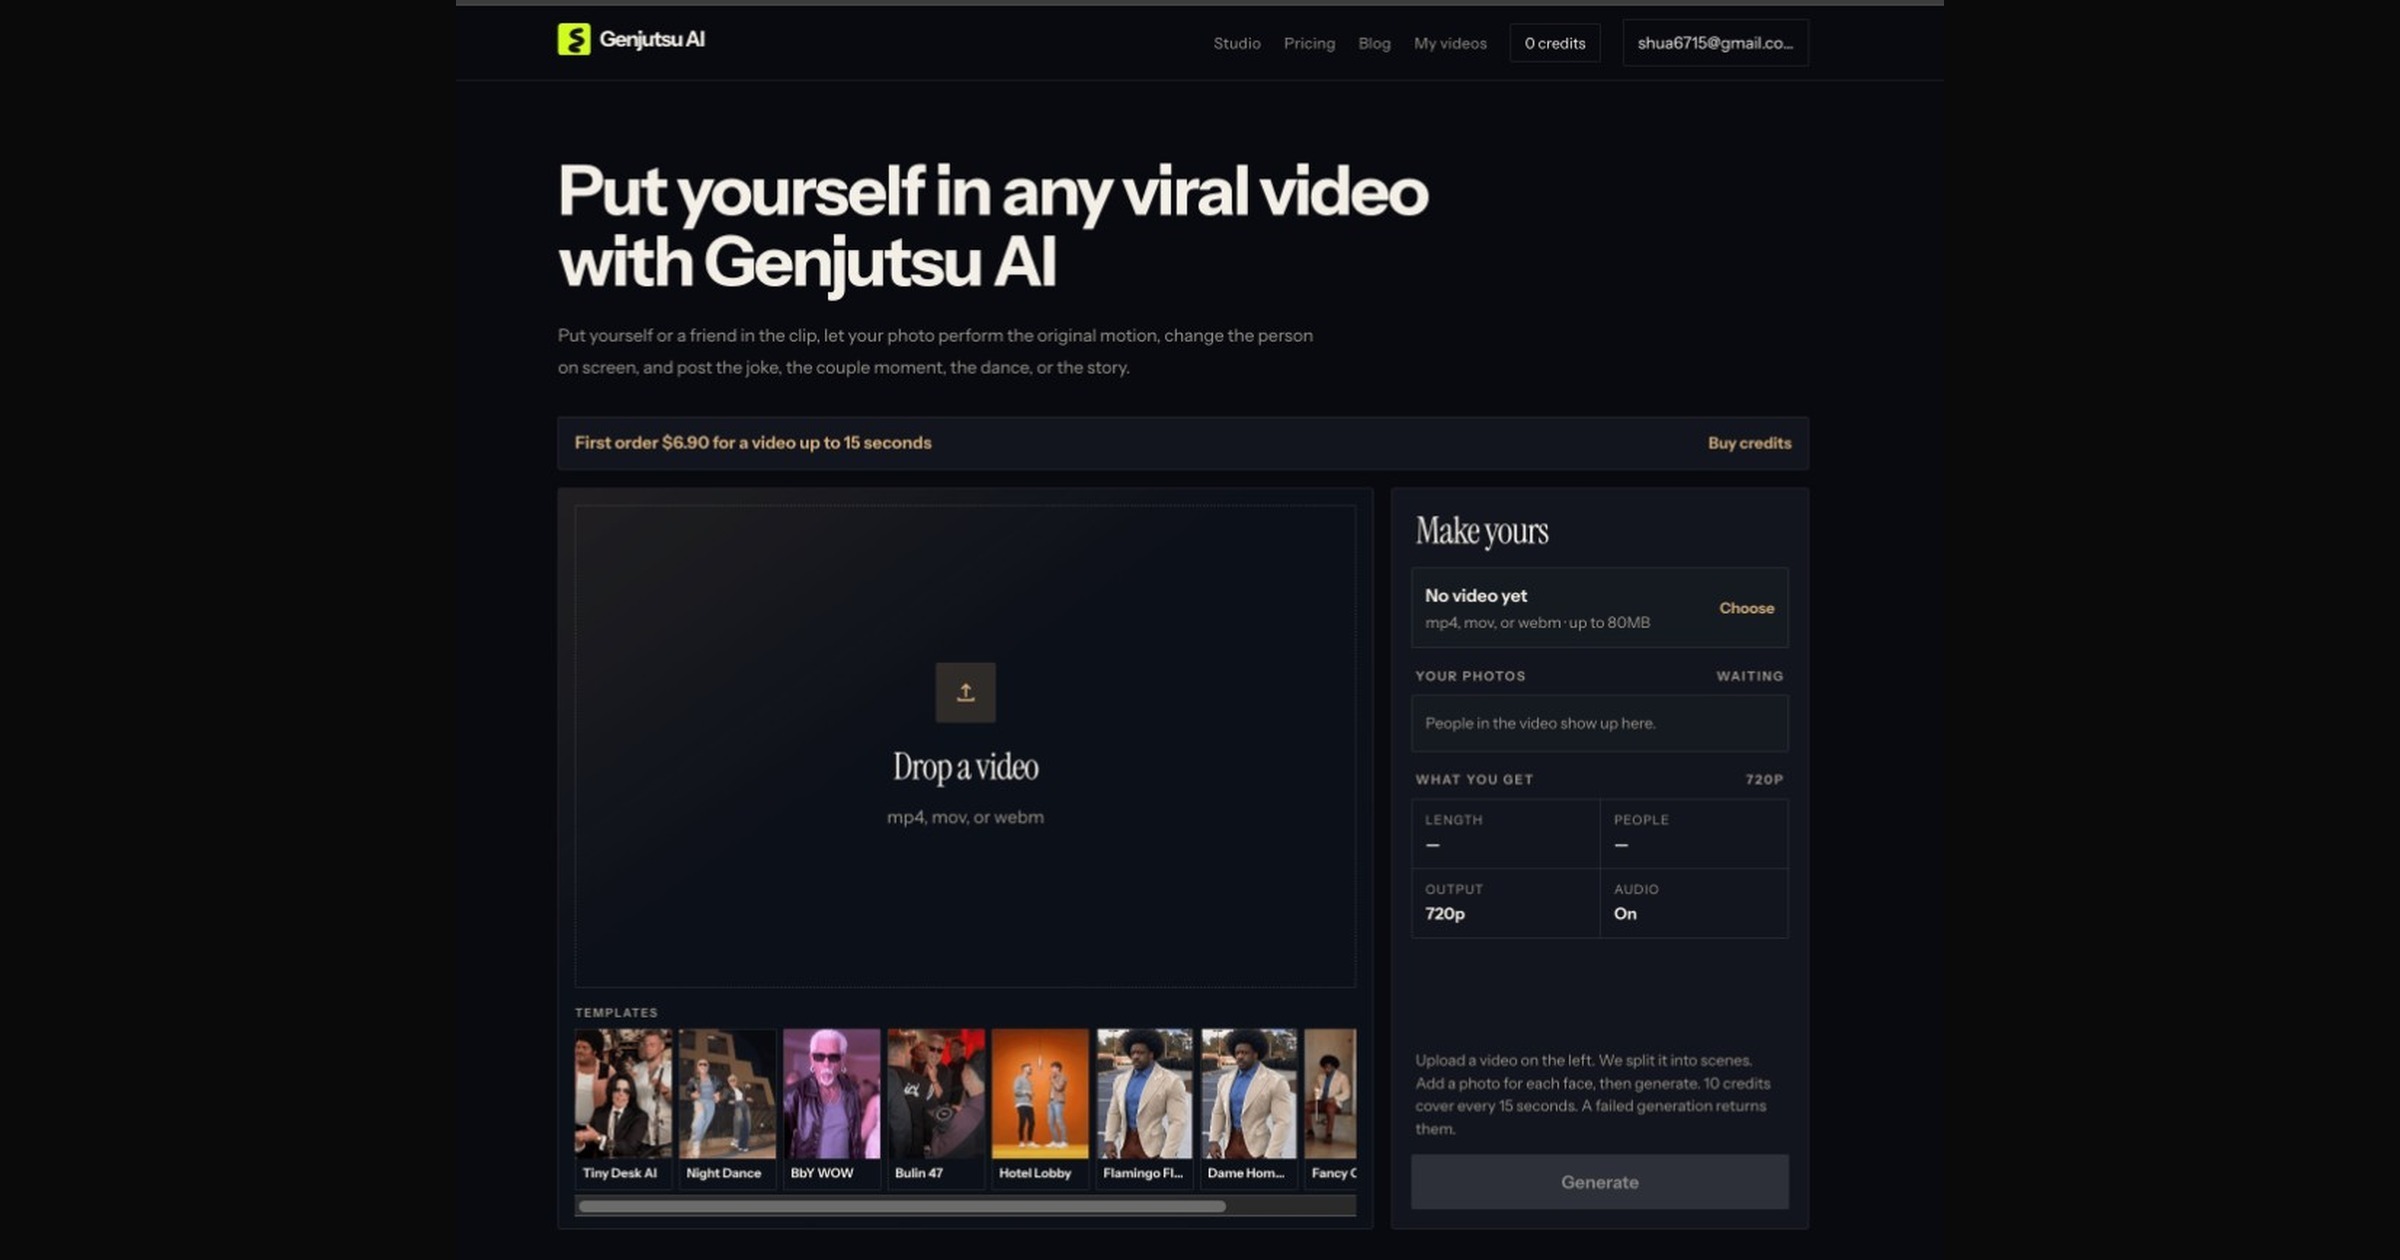

I shipped Genjutsu AI because I kept seeing the same workflow on social: someone wants to be inside a dance or meme that’s already everywhere, but they don’t want to lose the song, the timing, or the camera from the original file.
This is not “type a prompt, get a new video.” You bring the clip. Genjutsu reads the take, finds who’s on screen, and lets you attach one still photo per person you want to replace. That photo stays the same person across every shot they appear in. Everyone else, the location, and the props stay as filmed.
What stays the same
Shot order, timing, and camera
Cuts and pacing
Original audio (music and vocals on the same beat)
What changes
Only the people you assign a photo to — you, a friend, a pet, a product, or a character.
How it works
Upload mp4, mov, or webm (up to 80MB), or start from a template (Hotel Lobby, Tiny Desk AI, Night Dance, Bulin 47, Dame Hombro, BbY WOW).
Scenes and faces are detected automatically.
Attach one photo per person you want in the frame.
Generate and download 720p with the source audio.
Pricing (before you click Generate)
10 credits per 15 seconds of video
Failed generations refund credits
Sign in with Google so jobs stay on your account
First 15-second run on Starter is $6.90, then $9.99 for 10 credits — pricing
Tip: Keep a single scene under 15 seconds for the smoothest first test.
Stack (if you care)
Next.js 16, Python cast pipeline for scene/face work, Prisma + Postgres, object storage for uploads, Stripe credits, and a video model API for the swap. Happy to go deeper in the comments.
Not Higgsfield Genjutsu
Genjutsu AI is a separate product: your video + your photos. Same filmed motion, different faces.
Try it
https://ai-genjutsu.com/ — drop a short clip and one photo.
I’d love feedback on scene splits, face consistency across cuts, and whether the credit model feels fair for short-form creators.




Top comments (0)