
Text prompts are bad at describing a look. You can spend forty words on a colour palette and a lighting setup and still not land it, when the thing you actually want is sitting in a reference image on your desktop. Fooocus solves this with Image Prompt, a panel that lets you feed images in alongside the text and control exactly which part of each reference gets copied. This is how it works and how to set the two sliders that decide whether it helps or ruins the render.
Image Prompt is not img2img
The first thing to get straight, because it changes how you use the feature: Image Prompt does not start the diffusion process from your reference. In img2img, the reference image is noised and then denoised, so the output is anchored to the original composition whether you want that or not. Image Prompt instead converts the reference into conditioning that sits next to the text prompt and nudges the model as it generates. The layout is free to change completely.
That is why the results feel different. img2img gives you a variation on a picture. Image Prompt gives you a new picture that inherited something from a picture. Under the hood this is the IP-Adapter family of techniques - the reference implementation is public - wrapped in an interface that hides the model wiring. Fooocus downloads whichever auxiliary model a mode needs the first time you select it, so the first generation on a fresh install stalls for a while and then behaves normally.
The four modes and what each one actually copies
Open the Input Image panel, switch to the Image Prompt tab, and tick Advanced under a reference slot. You get a mode selector. Picking the wrong one here is the most common reason people conclude the feature does not work.
| Mode | What it transfers | Reach for it when |
|---|---|---|
| ImagePrompt | Overall style, palette, mood, texture | You want a different scene that feels like the reference |
| PyraCanny | Edges and hard outlines | You want to keep the exact shape or layout of the subject |
| CPDS | Structure, depth relationships and shading | You want the spatial arrangement without copying line detail |
| FaceSwap | Facial identity | You need the same person across several generations |
A quick way to remember it: ImagePrompt copies the vibe, PyraCanny copies the lines, CPDS copies the volumes, FaceSwap copies the face. If you load a photograph in ImagePrompt mode and complain that the composition is not preserved, you wanted PyraCanny or CPDS instead.
The two sliders that decide everything
Each reference slot has a Weight and a Stop At value, and they do genuinely different jobs.
Weight is how loud the reference is relative to your text prompt. Low weight and the reference is a suggestion. High weight and it starts overriding the prompt - you asked for a goat in a suit and got the reference image back with slightly different lighting.
Stop At is when the reference stops being applied, expressed as a fraction of the sampling run. This one is more useful than it looks, because a diffusion model decides composition early and detail late. Stop the reference at around a third and you get its layout with your own texture and finish. Let it run to the end and it drives the fine detail too.
The practical consequence is that structure and style want different Stop At values:
- For a structural reference (PyraCanny, CPDS): a lower Stop At is often enough. The shape is locked in during the early steps anyway, and releasing the constraint afterwards lets the model finish the surfaces properly.
- For a style reference (ImagePrompt): a higher Stop At keeps the palette and texture consistent through to the end, which is usually what you wanted from a style transfer.
Start both sliders near the middle, generate, and adjust one at a time. Moving both at once tells you nothing about which one mattered.
Stacking references
Fooocus gives you several reference slots, and each can run a different mode. That is where the feature earns its keep, because you can decompose a look into independent parts:
- Slot one: PyraCanny on a rough sketch or a photo whose framing you want. This fixes the composition.
- Slot two: ImagePrompt on a completely unrelated image whose colour and lighting you like. This paints the first slot's structure in the second slot's aesthetic.
- Slot three, only if you need it: FaceSwap on a portrait, to keep one identity consistent across a series.
- Write the text prompt for the content you want, not for the style - the references are already handling style. Redundant style words fight the references.
- Generate a batch, then adjust the weight of whichever slot is clearly winning too hard.
The failure mode is obvious once you have hit it: three strong references pulling in different directions produce an average, and averages are muddy. If an output looks vague rather than wrong, drop one reference entirely instead of rebalancing all three.
Other things that will bite you
- Aspect ratio mismatch. A portrait reference feeding a landscape render, especially in PyraCanny mode, produces stretched structure. Match the ratio where you can.
- Busy references. ImagePrompt on a cluttered photo transfers the clutter as a texture. Clean, graphically simple references transfer more cleanly.
- Over-specified prompts. If your text prompt already describes a full scene and your references describe a different one, the model splits the difference. Let one of them lead.
- Small faces. FaceSwap needs enough pixels on the face in both reference and output. A face occupying a small part of a wide shot will not hold identity.
A prompt to test the setup with
This one is a useful control because the subject is unambiguous and the style is entirely open, so whatever the reference contributes is easy to spot:
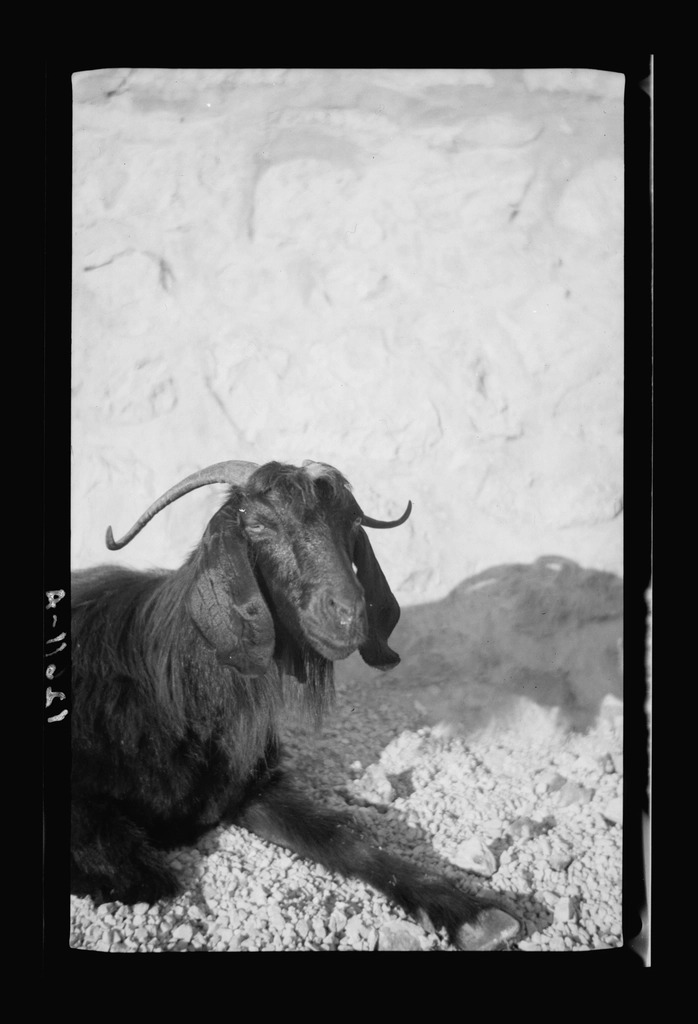
humanoid goat wearing a black suit, detailed photo, depicting everyday life
Run it once with no reference at all, then again with a single ImagePrompt reference at moderate weight. The delta between the two is your answer to what that reference is actually doing. Keep a generic quality-cleanup negative prompt alongside it on checkpoints that use guidance:
painting, drawing, illustration, glitch, deformed, mutated, cross-eyed, ugly, disfigured, 3D
Practical takeaways
Pick the mode by asking what you want copied - vibe, lines, volumes, or face - and most of the confusion around this feature disappears. Weight controls how hard the reference pushes; Stop At controls how long it pushes for, and structural references generally want to be released early while style references usually run long. Change one slider per generation so you can attribute the result. And when stacking references, give each slot a distinct job: one for structure, one for style, and stop there.




Top comments (0)